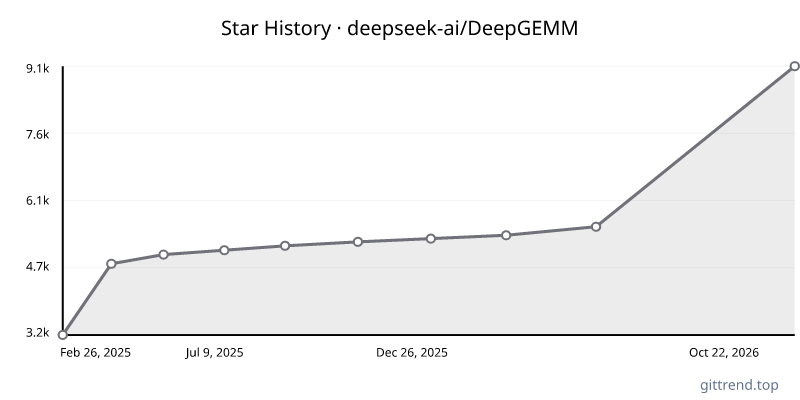
Overview
DeepGEMM is a high-performance, unified tensor core kernel library designed for modern large language models. It delivers highly optimized implementations of essential computations like GEMMs (FP8, FP4, BF16), fused MoE with overlapped communication (Mega MoE), MQA scoring, and HyperConnection (HC). Built with simplicity and efficiency in mind, DeepGEMM features kernels compiled at runtime via DeepJIT, eliminating the need for CUDA compilation during installation.
Key Features
- Runtime Compilation (DeepJIT): Kernels are compiled on demand, ensuring optimal performance for your specific hardware and configurations without build-time dependencies.
- Advanced Data Formats: Supports cutting-edge formats like FP8, FP4, and BF16 for GEMM operations, maximizing computational throughput.
- Fused MoE and Overlapped Communication: Features Mega MoE for fused expert dispatch, linear layers, SwiGLU activation, and expert combination, overlapping communication and computation for maximum efficiency.
- Optimized Indexing Kernels: Includes MQA scoring kernels for lightning indexers and supports both prefilling (non-paged) and decoding (paged) scenarios.
- Flexible Grouped GEMMs: Offers both contiguous (M-axis grouped) and masked (for dynamic inference) grouped GEMM APIs tailored for Mixture-of-Experts (MoE) models.
- High Performance: Achieves state-of-the-art performance, matching or exceeding expert-tuned libraries across various matrix shapes, including significant TFLOPS gains on high-end GPUs.
- Clean and Accessible Codebase: Inspired by CUTLASS and CuTe but with a focus on simplicity, making it an excellent resource for learning GPU kernel optimization.
- Extensive Utilities: Provides a rich set of utility functions for controlling SM usage, tensor core utilization, deterministic algorithms, and JIT compilation behaviors.
Typical Use Cases
- Training and Inference of Large Language Models: Accelerate the core GEMM operations, MoE routing, and attention mechanisms crucial for LLMs.
- Optimizing Sparse Models: Efficiently handle MoE architectures with fused operations and overlapped communication.
- Low-Latency Inference: Leverage paged MQA kernels and optimized GEMMs for decoding tasks.
- Research and Development: Serve as a foundational library for exploring and implementing novel LLM architectures and optimization techniques.
- GPU Kernel Optimization Learning: Provides a clean and well-structured codebase for understanding advanced NVIDIA GPU programming.