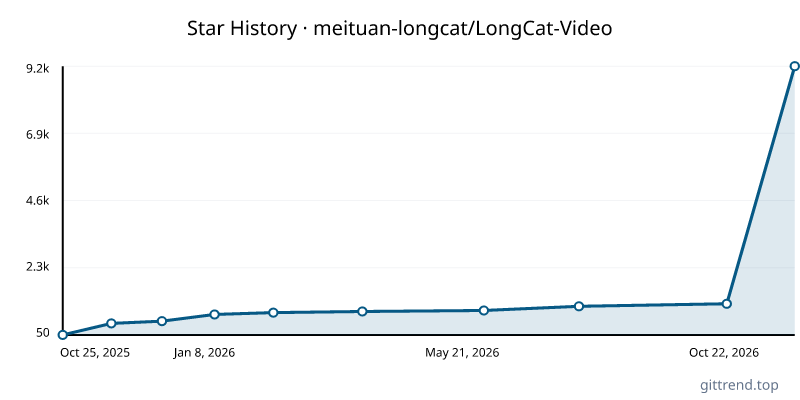
Overview
LongCat-Video is a groundbreaking 13.6B parameter foundational model for video generation. It achieves state-of-the-art performance across Text-to-Video, Image-to-Video, and Video-Continuation tasks, with a particular emphasis on generating high-quality, minutes-long videos efficiently. This release marks a significant step towards the development of sophisticated world models.
Key Features
- Unified Architecture: Seamlessly handles Text-to-Video, Image-to-Video, and Video-Continuation with a single, high-performing model.
- Extended Video Generation: Natively pretrained for Video-Continuation, enabling the creation of extended videos (minutes-long) without color drift or quality degradation.
- Efficient Inference: Generates $720p$, $30fps$ videos rapidly using a coarse-to-fine strategy and optimized Block Sparse Attention for enhanced efficiency at high resolutions.
- Advanced Training: Leverages multi-reward RLHF with Group Relative Policy Optimization (GRPO) for performance comparable to leading commercial and open-source solutions.
- Avatar Generation: Features specialized versions like LongCat-Video-Avatar and LongCat-Video-Avatar 1.5, offering advanced audio-driven character animation with impressive lip synchronization, stylistic generalization, and fast inference capabilities.
Typical Use Cases
- Creative Content Creation: Generate dynamic video content from textual descriptions or static images for marketing, social media, or artistic projects.
- Storyboarding and Animation: Quickly prototype and visualize video sequences, ideal for filmmakers and animators.
- Interactive Media: Develop engaging audio-driven character animations for virtual assistants, gaming, or educational platforms.
- Video Editing and Enhancement: Extend existing video clips with coherent and high-quality continuations.
- Research and Development: Serve as a powerful base model for further exploration in video generation and world modeling.